Operations · Management
GPU Cluster Operations: Management Access, Power and Spare Parts
Complete a GPU-cluster deployment with independent recovery access, failure-state power planning, exact replacement parts and operational records.
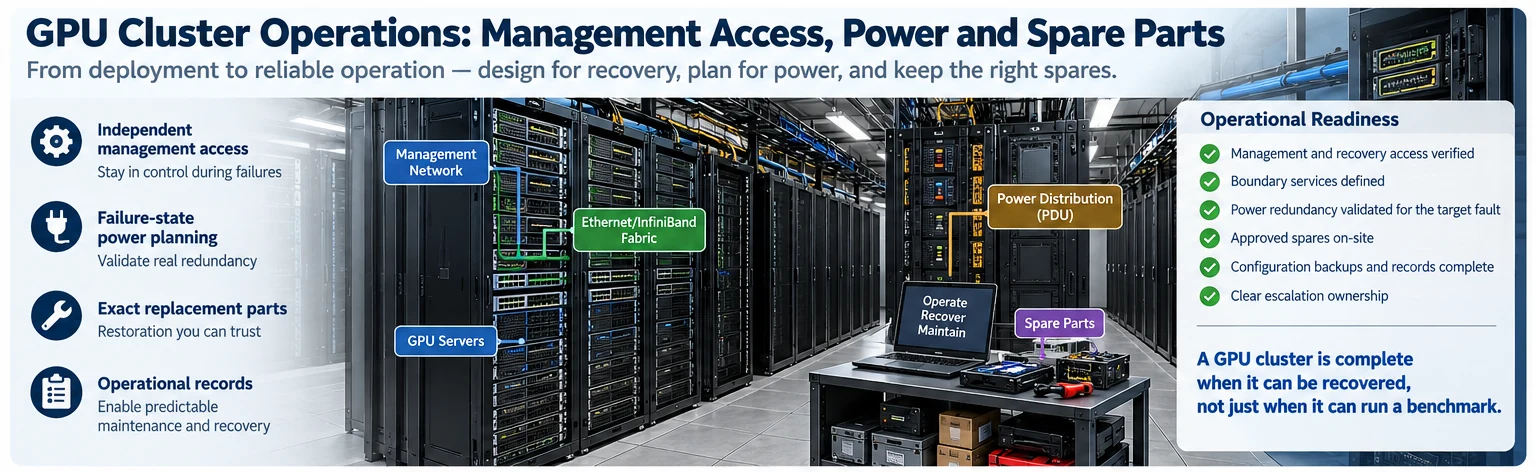
A compute fabric can pass its first traffic test and still be difficult to operate. Missing console access, an unqualified spare fan or two “redundant” supplies on the same feed may not appear in a bandwidth benchmark. They become important when a technician must recover the cluster.
The operational layer should therefore be designed alongside the high-speed network. Its purpose is to make installation, diagnosis, maintenance and recovery predictable.
Build a recovery path that survives the target fault
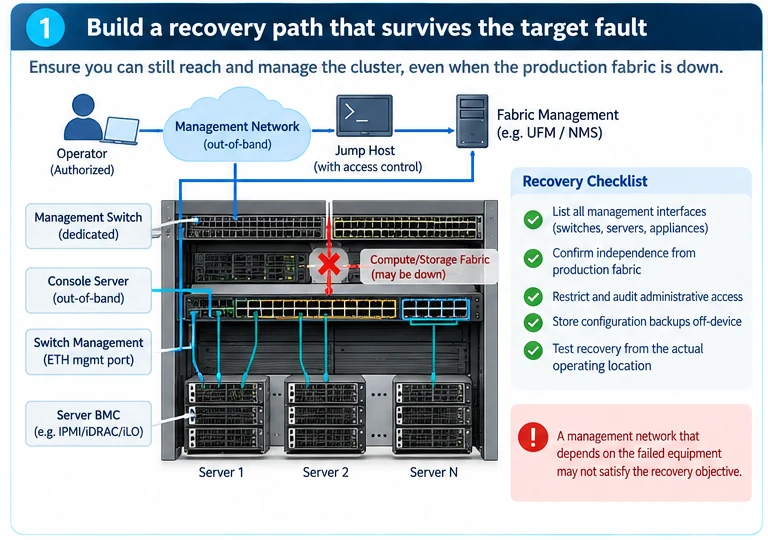
List switch management interfaces, server management controllers, console connections, fabric-management services and the administrative access path. Draw their dependencies on switching, power, authentication and name resolution.
A useful recovery exercise is to remove the production fabric from the drawing. Can an authorized operator still identify the failed device, reach its management plane and retrieve the necessary configuration? A management VLAN that depends on the failed equipment may not satisfy that objective.
Apply access controls to the management network, restrict administrative entry points and retain configuration backups outside the device being protected. Test access from the actual operating location rather than only from a laptop beside the rack.
Define boundary services precisely
“Gateway” can refer to several different functions: routed access, a storage service, an application proxy or a supported InfiniBand/Ethernet gateway implementation. Describe what traffic must cross the boundary, which protocol terminates where and which component owns the translation or service.
Do not add a generic gateway appliance to the BOM and assume it transparently converts every workload. Include authentication, monitoring and recovery responsibilities for the selected service.
Engineer the failure-state power budget
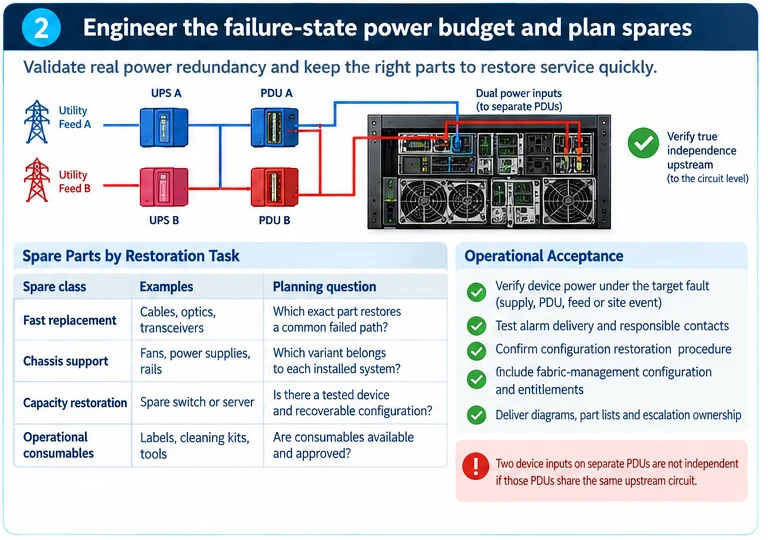
Build a device-to-PDU-to-feed map. Calculate the populated equipment load, including installed optics and adapters, against the available power arrangement. Then evaluate the exact failure the design claims to tolerate: a supply, a PDU, a feed or a larger site event.
As an illustrative dependency check, two device inputs connected to separate PDUs are not independent if both PDUs ultimately depend on the same unprotected circuit. The drawing must show the upstream boundary, not stop at the rack outlets.
Installation and replacement procedures remain specific to the equipment. NVIDIA’s FRU documentation makes replacement conditions part of the system procedure; the label “field replaceable” does not authorize an arbitrary live swap. R09
Stock spares by restoration task
| Spare class | Planning question |
|---|---|
| Fast replacement | Which approved cable, optic or assembly restores a common failed path? |
| Chassis support | Which exact fan, supply or rail variant belongs to each installed system? |
| Capacity restoration | Is there a tested replacement device and a recoverable configuration? |
| Operational consumables | Are labels, cleaning materials and approved handling tools available? |
Choose quantities from failure impact, replacement lead time and the desired recovery window rather than applying one percentage to every part. Label spares with the installed configurations they can replace. Segregate failed and serviceable stock.
Commission operations as a separate deliverable
Test management reachability, log timestamps, alert delivery, configuration restoration and the documented replacement path. Confirm who receives an alarm and who is authorized to act on it. Where an appliance runs fabric management, include the service configuration and entitlement record in the handover, not just the appliance serial number. R52
The final operational package should contain the dependency diagram, administrative access procedure, power map, version baseline, backup location, approved spare list and escalation ownership. It should allow a different engineer to recover the system without relying on the memory of the installation team.
Engineering illustrations
These figures illustrate the design concepts discussed here. They are not measured results, certified configurations or a supplied-equipment list.
Related reading
- NVIDIA FRU Selection: Identify the Installed Variant Before Ordering
- Six Often-Missed Items Between a Network Quote and a Working Rack